Jev: The AI Model That Doesn’t Chat — It Makes Decisions - AppHall
Jev: The AI Model That Doesn’t Chat — It Makes Decisions
Jev is a new System One AI model from TypeSafe AI built for fast, structured decisions rather than conversation. Instead of generating text, it returns typed choices, scores, and probabilities—making it especially useful for AI agents, routing, guardrails, classification, and other high-frequency software decisions.
For years, the dominant interface for artificial intelligence has been remarkably consistent: give a model some text, let it think, and receive more text in return.
ChatGPT writes answers. Coding models generate programs. AI agents reason through tasks and propose actions. Even when software only needs a simple classification or routing decision, developers often reach for a large language model and ask it to return JSON.
Created by TypeSafe AI and released in early access in September 2026, Jev is the company's first System One Model: an AI model designed not for conversation or open-ended generation, but for fast, structured decisions inside software.
Instead of asking Jev to write an explanation, developers give it some state, define a question and a bounded set of possible answers, and receive typed decisions accompanied by probabilities.
In other words, Jev is less like a chatbot and more like an intelligent decision function.
From Generating Language to Making Decisions
Consider a customer support application receiving this message:
"I was charged twice for my subscription."
A general-purpose language model could analyze the message, reason about it, generate a JSON object, and return something such as:
{ "department": "billing" }
That works, but it uses a system optimized for generating arbitrary language to produce a result that ultimately contains only one useful value.
Jev approaches the problem differently.
The application defines the possible destinations:
Billing Technical Support Sales Other
Jev evaluates the customer message and returns probabilities for the available choices. The application can then route the ticket according to its own rules.
This distinction is fundamental.
Traditional LLMs are primarily optimized for generation. Jev is optimized for judgment.
TypeSafe describes the model as accepting unstructured state and returning typed, probabilistic decisions. The surrounding application—not Jev—remains responsible for deciding what action to take.
That separation between AI judgment and software policy is one of the project's most important ideas.
The term comes from the distinction popularized by psychologist Daniel Kahneman between two modes of thinking.
System 1 is fast, intuitive, and automatic. System 2 is slower, deliberate, and analytical.
TypeSafe borrows this terminology to describe a class of models built for rapid judgments rather than extended reasoning.
Today's reasoning models increasingly resemble System 2. They may generate long reasoning traces, use tools repeatedly, search for additional information, verify intermediate results, and spend significant compute before producing an answer.
That is useful for difficult problems.
But many decisions inside software do not require this process.
An application may simply need to know:
Which department should handle this request?
Is this document relevant?
How urgent is this incident?
Is this proposed tool call dangerous?
Which AI model should handle this task?
Does this result require human review?
These decisions are too semantic for traditional if/else rules, yet often too small to justify a full reasoning-model invocation.
Jev is designed for this middle layer.
A New AI Primitive for Software
The easiest way to understand Jev is to compare it with a conventional LLM API.
The difference may appear subtle, but architecturally it is significant.
Jev deliberately gives up arbitrary string generation. It cannot write an essay, compose an email, generate source code, or freely explain its reasoning.
What it gains is a constrained output space that software can consume directly.
Vercel describes the practical distinction clearly: use Jev when an application needs to interpret information and select among defined outcomes; use a generative model when the application actually needs written language or code.
Choices, Scores, and Probabilities
Jev's interface centers on structured decision primitives rather than text completion.
A developer might ask it to make a choice:
Where should this support request go? - Billing - Account Access - Technical Support - Sales
Or evaluate something on an ordered score:
How urgent is this incident? 1 — Low 2 — Medium 3 — High 4 — Critical
Another useful pattern is estimating the probability of a proposition:
Does this message explicitly request a refund?
Instead of merely returning yes, the model can expose uncertainty.
The threshold belongs to the application, not the model.
Vercel specifically recommends establishing these thresholds using representative labeled examples rather than treating a probability number as an automatic permission to act.
Why Probabilities Matter
Confidence is often awkward with traditional language models.
You can ask an LLM, "How confident are you?" but the number it generates is still language. A model might confidently say "95%" without that figure being reliably calibrated against real-world accuracy.
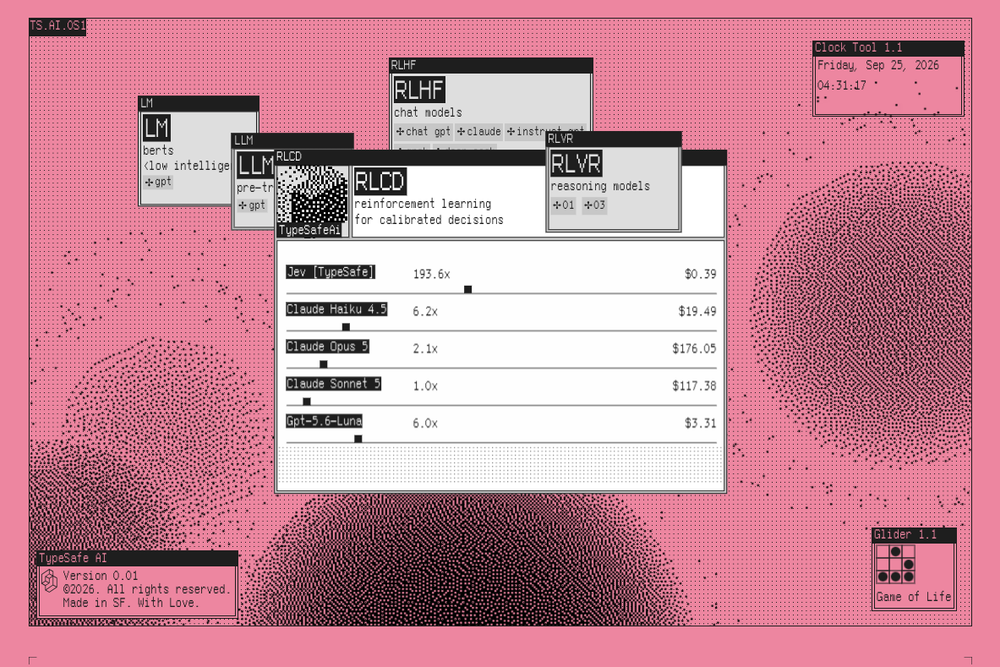
TypeSafe says Jev was trained specifically around probabilistic decisions using a method it calls Reinforcement Learning for Calibrated Decisions, or RLCD.
The goal is not merely to predict an answer, but to make uncertainty useful to software.
If probabilities are reasonably calibrated, developers can build workflows where different confidence ranges trigger different levels of automation.
Ambiguous cases can be escalated to a more capable model.
Risky or uncertain cases can go to a human.
This is important because production automation rarely requires every decision to be perfect. What matters is knowing which decisions are safe enough to automate and which require additional scrutiny.
TypeSafe presents calibrated uncertainty as one of Jev's key differences from conventional LLMs. Because these claims come from the model's creator, they still need broader independent validation across industries and workloads.
Why Jev Can Be So Fast
Large language models usually generate output autoregressively.
They produce one token, then another, then another. Longer outputs require more generation steps.
Jev does not generate prose.
Because its output space is bounded, TypeSafe says Jev can compute the relevant probabilities without going through a long token-by-token generation process.
The company reports end-to-end latency ranging roughly from tens to hundreds of milliseconds for its workloads, with some evaluations showing dramatically lower latency than frontier LLMs performing equivalent structured tasks.
TypeSafe's published workflow evaluations report peak improvements of approximately 193.6× faster and 444.6× cheaper in selected scenarios.
Those numbers should not be interpreted as universal benchmarks. TypeSafe itself says they represent the higher end of expected real-world gains, and the workflows were created internally.
The more important idea is structural: if an application only needs a small decision, avoiding language generation can eliminate a great deal of unnecessary computation.
The Most Interesting Use Case: AI Agents
Jev becomes particularly interesting when applied to AI agents.
Modern agents rarely make only one model call.
A typical loop might look like:
User Request ↓ LLM chooses action ↓ Tool executes ↓ LLM evaluates result ↓ LLM decides what to do next ↓ Repeat
Every judgment may require another expensive model invocation.
LangChain describes this as one of the major practical problems of agent systems: tool calling and structured outputs made agents easier to integrate into software, but repeated model decisions still create latency and cost.
Jev can potentially replace some of those lightweight decision calls.
For example, an agent might ask:
Is the retrieved document relevant?
Has enough information been collected?
Which model should handle the next step?
Does this tool invocation appear dangerous?
Should this task be escalated to a human?
The generative model still handles difficult reasoning and language generation. Jev operates around it as a fast control layer.
This leads to a useful architecture:
→ Fast Model User → Jev Router → Powerful Reasoning Model → Human Review
Instead of replacing LLMs, Jev may make them more efficient.
Model Routing
One particularly promising application is intelligent model selection.
Many AI products now have access to several models with very different costs and capabilities.
A simple customer request might only require a small, inexpensive model.
A complicated debugging problem might justify a powerful reasoning model.
Static rules such as prompt length are poor proxies for difficulty.
Jev can instead evaluate the task semantically:
How difficult is this request? Easy Medium Hard
The application can then route easy cases to cheaper models and reserve expensive reasoning for tasks that actually need it.
LangChain has already explored Jev in agent middleware for this kind of model routing and control logic.
Guardrails and Tool Approval
Another natural use case is agent safety.
Imagine an autonomous coding agent proposing a shell command that could modify or delete important files.
Before execution, Jev could evaluate:
Is this tool call potentially destructive?
The resulting probability becomes one signal in an application-controlled policy.
A low-risk action might execute automatically.
A questionable one might require user confirmation.
A dangerous one could be blocked.
Importantly, Vercel recommends keeping permissions, argument validation, and tool execution in application code. Jev provides a judgment—it should not become the security boundary itself.
Why Not Just Use a Classifier?
At first glance, Jev may sound like an ordinary machine-learning classifier.
There is an important difference.
Traditional classifiers are usually trained for a specific task:
spam / not spam
Changing the task may require new training data and another model.
Jev attempts to provide frontier-style semantic understanding while allowing developers to define new decision spaces at runtime.
The same model might classify support tickets today, judge document relevance tomorrow, and score agent actions the next day.
In that sense, Jev can be thought of as a general-purpose semantic classifier with a programmable decision interface.
It aims to occupy the flexibility gap between hand-built classifiers and fully generative LLMs.
Why Not Use LLM Structured Outputs?
This is probably Jev's most important competitive question.
Modern LLM APIs already support structured outputs and JSON schemas.
A developer can instruct a model to return:
{ "department": "billing", "confidence": 0.91 }
So Jev's advantage is not simply that it produces structured data.
The argument is architectural.
A conventional LLM is fundamentally a language generator being constrained into a decision interface.
Jev starts with the decision interface itself.
If TypeSafe's claims hold broadly, that specialization can translate into lower latency, lower cost, fewer schema failures, and more useful probability estimates.
Whether those advantages justify adopting a separate model will depend heavily on the workload.
For occasional classifications, a developer may reasonably prefer keeping everything inside an existing LLM stack.
At large scale, where millions of tiny semantic decisions occur every day, the economics can look very different.
Typed Does Not Mean Correct
One of the most important distinctions surrounding Jev concerns hallucination.
TypeSafe says Jev cannot hallucinate in the sense that it cannot generate arbitrary values outside the defined output space.
If the permitted answers are:
A B C
Jev cannot suddenly return:
D
That is an extremely useful type-safety property.
But it does not mean Jev cannot be wrong.
The model can return a perfectly valid B when the correct answer was A.
Vercel explicitly warns that typed output does not guarantee a correct decision and recommends testing Jev against representative known outcomes before connecting it to consequential actions.
The distinction is:
output validity is not decision correctness.
That principle matters for any production system built around probabilistic AI.
Where Jev Fits Best
Jev is most compelling when three conditions are present:
The application needs semantic understanding.
The set of useful outcomes is bounded.
The decision occurs frequently enough that latency or cost matters.
Potential applications include:
Customer support routing
Fraud and risk scoring
Content moderation
Lead qualification
Retrieval relevance checks
AI model routing
Agent tool approval
Workflow branching
Incident prioritization
Human-review escalation
Recommendation filtering
Automated evaluation
These are exactly the kinds of decisions that often sit awkwardly between rigid rules and heavyweight generative AI.
What Jev Is Not
Jev is not a replacement for GPT-style models.
It is poorly suited to tasks such as:
Writing articles
Producing explanations
Generating code
Brainstorming
Open-ended research
Complex multi-step reasoning
If the output itself is language, a language model remains the obvious tool.
Jev is useful when language is merely the input, while the desired output is a decision.
A Different Vision for AI
The most interesting thing about Jev may not be its benchmark numbers or even the model itself.
It is the idea of AI becoming an invisible primitive inside ordinary software.
The first wave of modern generative AI was dominated by chatbots:
AI = conversation
Then came copilots:
AI = assistant
More recently, agents have pushed toward:
AI = autonomous worker
Jev suggests another direction:
AI = software primitive
Instead of interacting with the model directly, users may trigger hundreds of tiny AI decisions without ever knowing they happened.
An application could call intelligence in much the same way it queries a database, checks a cache, or evaluates a rule.
That may ultimately be where System One Models matter most.
Jev does not attempt to be an AI that can do everything. It deliberately does less: no conversation, no essays, no open-ended generation.
In exchange, TypeSafe is betting that a specialized model can make the countless small judgments hidden inside modern software much faster and cheaper.
Whether Jev itself becomes a major platform remains uncertain. Its strongest claims still need broader independent testing, especially around calibration, reliability, adversarial inputs, and performance across domains.
But the underlying question it raises is compelling:
If software only needs a decision, why are we asking an AI to write an answer first?
That question could prove more important than Jev itself.